
Share this post


See, predict, respond: Building resilient supply chains in an era of constant disruption
in partnership with
Supply chain disruption is now a perennial challenge. From geopolitical instability and extreme weather events to inflationary pressures, cyber threats and shifting customer demand, volatility has become a permanent feature of the operating environment.
In response, organisations are rethinking traditional approaches to supply chain management. The focus is shifting from efficiency alone towards resilience, adaptability, and faster decision-making. Yet many businesses still struggle with fragmented data, limited visibility across complex supplier networks and an inability to anticipate disruption before it impacts performance.
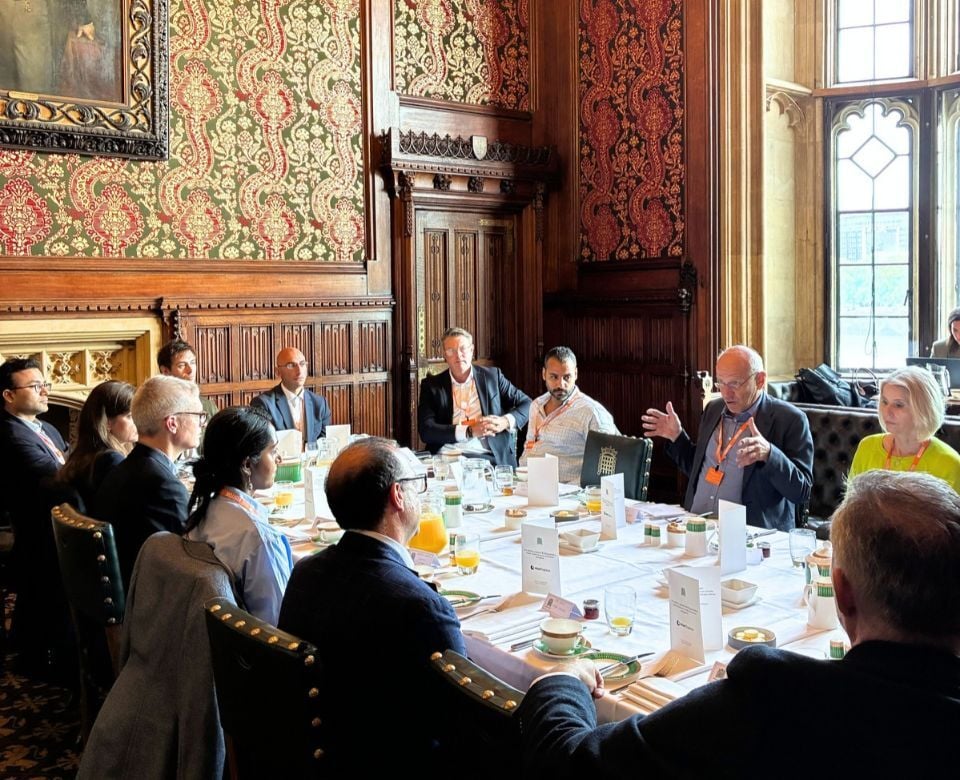
HotTopics and Hitachi Vantara brought senior IT, security, data and engineering leaders together at The House of Commons, London, to explore how they are building supply chains that can see risks sooner, predict outcomes more accurately and respond more effectively when disruption occurs.
This roundtable is part of the Leading with uncertainty series; co-moderating this session was Leading with uncertainty Advisory Board member, Jeffrey Wood, Deputy Director of ICT, Princess Alexandra Hospital NHS Trust.
Nine takeaways for HotTopics C-suite readers:
1. Measure supply-chain visibility by the decisions it changes
One of the most revealing examples came from a leader who described a previous organisation spending around £1 million annually assessing hundreds of suppliers. When a non-executive director asked whether the exercise had ever changed a procurement decision, the answer was no. Supplier assessments, dashboards and data lineage can all improve visibility, but their value depends on whether the information influences decisions.
Practical takeaway: Ask which supplier decisions have changed in the past 12 months because of new risk intelligence. If the answer is none, the organisation may be gathering information it cannot act upon.
2. Prioritise the suppliers that determine whether the business can recover
This debate challenged the ambition of achieving complete end-to-end visibility. One approach discussed was to classify critical suppliers according to the organisation's return-to-operation requirements.
Services needed within 24 hours of an incident received greater scrutiny, regardless of supplier spend.
That changes the basis of supplier-risk management. A relatively inexpensive service might be more critical to business continuity than a major commercial contract.
Practical implication: Start with the services the business must restore first. Identify every supplier supporting those services, including important subcontractors, and prioritise assurance accordingly.
3. Every efficiency gain deserves a concentration-risk assessment
A former NHS technology leader described reducing an application estate from roughly 500 systems to fewer than 130. The consolidation improved efficiency, but increased the consequences of failure in the remaining applications.
A cybersecurity executive described a similar dilemma from another direction. After an incident in which an alert went unaddressed for 58 hours amid excessive security noise, the organisation consolidated its security tools into a small number of platforms. That improved its ability to detect threats while increasing dependence on those providers.
Neither example produces a simple argument for diversification or consolidation.
Practical implication: Make concentration risk an explicit part of every major consolidation business case. Boards should understand the operational benefits alongside the consequences of losing a chosen platform.
4. Resilience depends on alternatives that can actually be activated
Participants repeatedly returned to optionality. Secondary suppliers, hybrid infrastructure, additional inventory and contractual exit provisions all have potential value.
But a nominal alternative is different from an operational one. Switching technology platforms can involve data migration, legal restrictions, specialist skills and lengthy implementation work. The discussion of major cloud and data-platform dependencies made clear how difficult such changes can be.
Practical implication: For each critical dependency, establish how long a switch would really take, what it would cost and whether the alternative has been tested. A second supplier named in a contingency plan is insufficient assurance on its own.
5. Build the ability to respond to events that forecasting misses
The discussion was sceptical about organisations' ability to predict the next major disruption, even with better data and AI.
One participant recalled extensive risk planning for the opening of an airport. The team had spent days identifying possible failures but missed the operational problem that actually occurred.
The lesson was to develop organisations capable of handling the unexpected. Participants pointed towards faster decision-making, rehearsed recovery and clearer authority to act.
Practical implication: Test leadership teams against plausible but unanticipated disruptions. Measure how quickly they identify the problem, make decisions and restore essential operations.
6. AI improves prediction, but accountability becomes harder as systems begin to act
The roundtable distinguished between AI that forecasts an event and AI that automatically decides what to do about it.
Participants discussed the value of historical and real-time data, alongside the risks of relying on models trained on unusual periods such as the pandemic. As the discussion moved towards autonomous agents, questions arose about who would be accountable for their decisions and how meaningful human oversight could operate at scale.
There was no settled answer.
Practical implication: Before allowing AI to execute consequential decisions, establish who authorises its deployment, how its performance will be monitored and when a human must intervene. Prediction accuracy alone is an inadequate approval criterion.
7. Technology procurement now requires geopolitical judgement
Participants described customers reconsidering US technology dependencies, evaluating sovereign infrastructure and asking whether suppliers operate in politically dependable jurisdictions.
The discussion also exposed the limits of such choices. Global supply chains remain intertwined, especially in semiconductors, raw materials and cloud infrastructure. A decision to favour a particular jurisdiction can reduce one exposure while introducing others.
Practical implication: Include geopolitical scenarios in reviews of strategically important suppliers. Assess where critical infrastructure, data and production capacity actually sit, and how changes in international relationships could affect access.
8. Some supply-chain risks have become matters of public policy
The debate raised a difficult question: what should a business do when it discovers a critical dependency for which no practical alternative exists?
National communications infrastructure and concentrated technology markets were discussed as examples. One participant proposed a government-backed assurance mechanism for technology suppliers, comparable in principle to a recognised certification mark.
The underlying argument was that certain risks are too large for individual enterprises to resolve. Yet participants also recognised that government regulation often develops more slowly than technology markets change.
Practical implication: Distinguish between risks the enterprise can manage, those requiring supplier or industry collaboration, and those requiring engagement with government or regulators. Escalate systemic dependencies rather than leaving them indefinitely on an internal risk register.
9. Boards need to agree what level of resilience they are prepared to pay for
Running through the entire conversation was a commercial tension. Additional inventory costs money. Maintaining alternative suppliers introduces complexity. Duplicating infrastructure can appear inefficient until the primary service fails.
Participants questioned how boards should balance profitability, resilience and recovery speed, particularly when different executives have different priorities.
This suggests that resilience needs to be treated as an explicit investment decision, with a defined tolerance for disruption.
Practical implication: Agree which services must survive a major supplier failure, how quickly they must recover and what the business is prepared to spend to achieve that outcome. Give the CFO, CIO, CISO and operational leadership a shared basis for making those trade-offs.
To join future C-suite events in this series, Leading with uncertainty, search HotTopics events calendar here.


Join the community
To join the HotTopics Community and gain access to our exclusive content, events and networking opportunities simply fill in the form below.
